Archive post
Core services - the block log revolution is here!
It's official now, you can configure your hived node to get rid of some of the 490+ gigabytes of compressed block log burden
## Dude, where did my block go?
It's official now, you can configure your hived node to get rid of some of the 490+ gigabytes of compressed block log burden. You can even shed all of it, but do you really want to and what if you change your mind?
### The time of no choice is over
Since the beginning of Hive blockchain (and its predecessor) there was that huge single file named block_log, mandatory for all nodes. A single file with a size of over 490 gigabytes now, requiring continuous disk space of its size. The block log revolution that comes into force with `1.27.7rc0` tag brings following improvements:
- Multiple one-million-block-each block log files can be used instead of a legacy single monolithic file.
- You can keep all of the files or only a number of most recent ones.
- Complete wipeout of block log is possible too, leaving you with one last block only kept in memory.
### The pros and cons
Let's examine the new modes in detail:
- Split mode - keeps each full block from genesis, hence provides full functionality of e.g. block API & **allows blockchain replay**. At the same time its 1M-blocks part files of block log may be physically distributed to different filesystems using symlinks which allows to e.g. keep only the latest part files on fast storage. Good for API node.
- Pruned mode - a variation of split mode, which keeps only several latest part files of block log. **Replay is no longer guaranteed**. Provides only partial functionality of block API & others - handles requests for not-yet-pruned blocks, e.g. serves latest several months of blocks through `block_api`. Good for transaction broadcaster.
- Memory-only mode - the ultimate pruning - no block log files at all, only single latest irreversible block held in memory. **Unable to replay** obviously. Unable to provide past blocks through block API & similar.
### The summary of block log modes
| mode name | blocks kept | replayable | the value of `block-log-split` option in config.ini |
| --- | --- | --- | --- |
| legacy | all | yes | -1 |
| split | all | yes | 9999 (default value now) |
| pruned | last n millions | sometimes | n > 0 |
| no-file | last 1 | no | 0 |
Wait a minute, you may say, the split mode number (9999) meets the condition of pruned one (> 0), there must be a mistake here. Let me explain in detail then - positive value of `block-log-split` option defines how many full millions of last irreversible blocks are to be kept in block log files. It means that when you set it to e.g. 90, all blocks will be kept for the time being, because Hive's got a little over 89 millions of blocks now. Thus for the time being the block log is not _effectively pruned_. After a while however, when the threshold of 90 millions is crossed, the file containing oldest (first) million of blocks will be pruned (deleted) and from that moment the block log will be _effectively pruned_. As you can see the boundary between split & pruned modes is blurred, but setting it to the biggest possible number (9999) means that your block log won't be pruned for the next 950+ years.
Now we're getting to the question why replay is available _sometimes_ in pruned mode. Full replay (from block #1) requires **all** blocks to be present in block log, therefore it can be performed as long as block log is **not** _effectively pruned_ due to combination of `block-log-split` value in configuration and current head block of the blockchain. After the oldest part file containing initial 1 million blocks is removed, the block log is _effectively pruned_ and full replay is no longer possible.
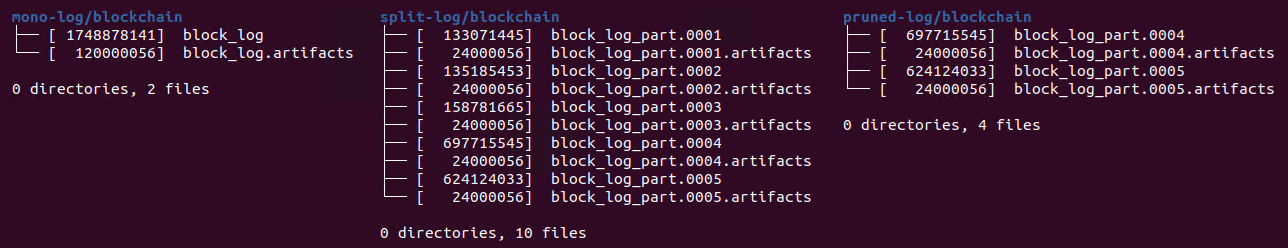
Block log files of nodes configured with different values of block-log-split option. Note the file size differences.
### Tips & tricks
- There are two ways to obtain split block log files from legacy monolithic one - a) Using `block_log_util`'s new `--split` option or b) running hived configured to have split block log with legacy monolithic one provided in its `blockchain` directory, which triggers built-in auto-split mechanism. The former is recommended as it allows to generate the 490+ GB of split files into output directory other than the source one (possibly on different disk space).
- All files of split/pruned block log, except the head one (the latest one, with highest number in filename) can be made read-only as they won't be modified anymore. The head file needs to be writable as it's where the new blocks are applied to.
- Split block log allows to scatter its part files over several disk spaces and symlink them all in hived's `blockchain` directory. Not only can smaller disk volumes be used, you can even consider placing older parts (i.e. the ones rarely used by hived) onto slower drives.
- The names of split/pruned block log files follow the pattern `block_log_part.????` where `????` stands for consecutive numbers beginning with `0001` followed by `0002`, etc. Since each one contains up to a million of blocks, `block_log_part.0001` contains blocks numbered `1` to `1 000 000`, while `block_log_part.0002` contains blocks numbered `1 000 001` to `2 000 000` and so on. Hived recognizes the block log files by their names, so don't change them or it becomes lost.
### Links and resources
- Source code version containing the improvements - https://gitlab.syncad.com/hive/hive/-/tags/1.27.7rc0
### Your feedback is invaluable and always welcome.