As you can see here, I have some links in my blogs written before the hive-fork pointing to steemit.com. It's time to replace them all.
Almost all blog posts written before the fork are written with apps that are not included in [hivescript](https://www.npmjs.com/package/@hivechain/hivescript) and lead to problems with canonical URLs:
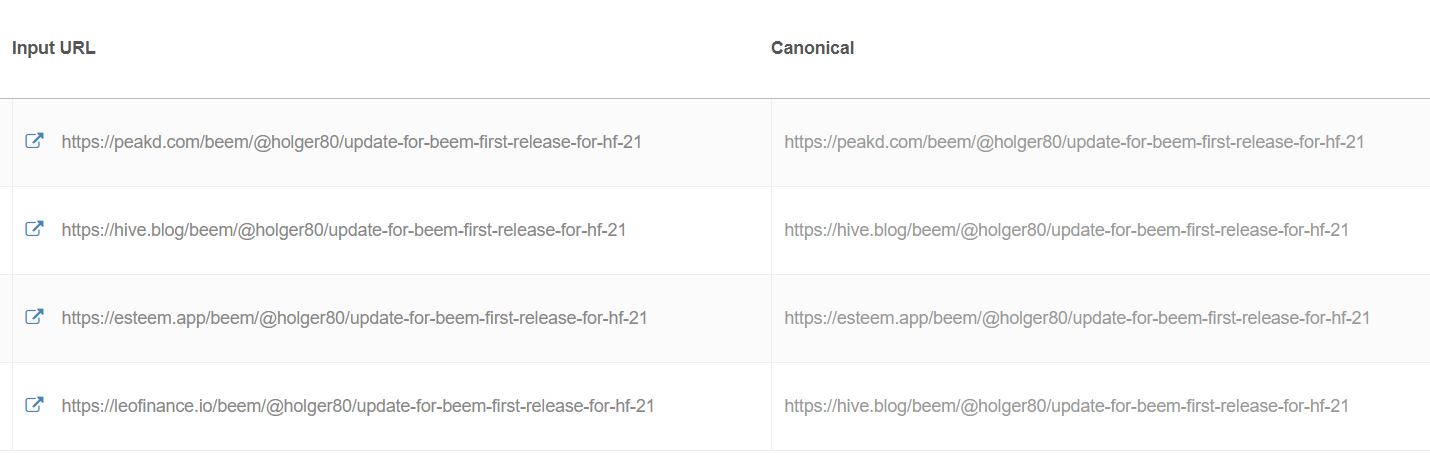
As it can be seen here, my old post [update for beem: first release for HF 21](https://peakd.com/beem/@holger80/update-for-beem-first-release-for-hf-21) result in different canonical URLs on different front-ends. This is then handled as duplicated content by the search engines.
The post was written through palnet. As there is no entry for palnet in [hivescript](https://www.npmjs.com/package/@hivechain/hivescript), the front-ends to not know how to build a proper canonical URL:
# Fixing The mess
Fixing means:
* replacing all steemit, steempeak, ... links with with links pointing to hive.blog
* setting `canonical_url` for each post written before 2020-03-20, to fix canonical URLs.
The following script is using beem and will do exactly this.
beem can be installed by
```
pip install beem
```
or
```
conda install beem
```
Store the following as `fix_canonical_urls_hive.py`:
```
#!/usr/bin/python
from beem import Hive
from beem.utils import addTzInfo
from beem.account import Account
from beem.comment import Comment
from beem.nodelist import NodeList
import time
from datetime import datetime
import getpass
if __name__ == "__main__":
nodelist = NodeList()
nodelist.update_nodes()
test_run_answer = input("Do a test run? [y/n]")
if test_run_answer in ["y", "Y", "yes"]:
test_run = True
print("Doing a test run!")
else:
test_run = False
if test_run:
hive= Hive(node=nodelist.get_hive_nodes())
else:
wif = getpass.getpass(prompt='Enter your posting key.')
hive= Hive(node=nodelist.get_hive_nodes(), keys=[wif])
account = input("Account name=")
account = Account(account, blockchain_instance=hive)
print("Start to fix canonical_url for %s" % account["name"])
canonical_url = "https://hive.blog"
apps_with_cannonical_url = ["hiveblog", "peakd", "esteem", "steempress", "actifit",
"travelfeed", "3speak", "steemstem", "leofinance", "clicktrackprofit",
"dtube"]
hive_fork_date = addTzInfo(datetime(2020, 3, 20, 14, 0, 0))
blog_count = 0
expected_count = 100
while expected_count - blog_count == 100:
for blog in account.get_blog_entries(start_entry_id=blog_count, raw_data=False):
blog_count += 1
if blog["parent_author"] != "":
continue
if blog["author"] != account["name"]:
continue
if "canonical_url" in blog.json_metadata and canonical_url in blog.json_metadata["canonical_url"]:
continue
if "app" in blog.json_metadata and blog.json_metadata["app"].split("/")[0] in apps_with_cannonical_url:
continue
if blog["created"] > hive_fork_date:
continue
body = blog.body
if "links" in blog.json_metadata:
links = blog.json_metadata["links"]
else:
links = None
if "links" in blog.json_metadata:
for link in blog.json_metadata["links"]:
if "steemit.com" in link or "steempeak.com" in link or "busy.org" in link or "partiko.app" in link:
authorperm = link.split("@")
hive_acc = None
hive_post = None
new_link = ""
if len(authorperm) == 1:
continue
authorperm = authorperm[1]
if authorperm.find("/") == -1:
try:
hive_acc = Account(authorperm, blockchain_instance=hive)
new_link = canonical_url + "/@" + hive_acc["name"]
except:
continue
else:
try:
hive_post = Comment(authorperm, blockchain_instance=hive)
new_link = canonical_url + "/" + hive_post.category + "/" + hive_post.authorperm
except:
continue
if new_link != "":
for i in range(len(links)):
if links[i] == link:
links[i] = new_link
body = body.replace(link, new_link)
print("Replace %s with %s" % (link, new_link))
json_metadata = blog.json_metadata or {}
json_metadata["canonical_url"] = canonical_url + "/" + blog["category"] + "/@" + blog["author"] + "/" + blog["permlink"]
if links is not None:
json_metadata["links"] = links
print("Edit post nr %d with canonical_url=%s" % (blog_count, json_metadata["canonical_url"]))
print("---")
if not test_run:
try:
blog.edit(body, meta=json_metadata, replace=True)
except:
print("Skipping %s due to error" % blog.authorperm)
time.sleep(6)
expected_count += 100
```
You can now start the script with:
```
python fix_canonical_urls_hive.py
```
If you are on Linux, you should replace `pip` by `pip3` and `python` by `python3`.
## How does it work
The script goes through all blog posts written before 2020-03-14. Whenever the post was written by an app, that is not properly handled by [hivescript](https://www.npmjs.com/package/@hivechain/hivescript), a new canonical_url is set.
You can define your preferred front-end here:
```
canonical_url = "https://hive.blog"
```
If you like other front-ends, you can replace this line by
* `canonical_url = "https://peakd.com"`
* `canonical_url = "https://leofinance.io"`
* `canonical_url = "https://esteem.app"`
In the next step, all used links are checked. Whenever a link is pointing to a valid hive post or to a valid hive user, the link is replaced by the url defined in `canonical_url` (When the link was pointing to steemit.com, steempeak.com, busy.org or partiko.app).
## Test run
You can do a test run and checking what will be changed by the script:
This show now the following information:
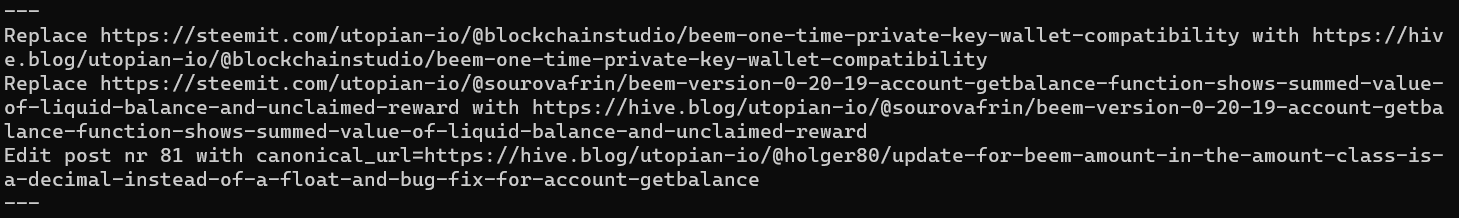
The set canonical url is shown as well all links that will be replaced.
## Fixing your posts
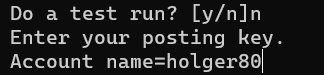
We can now start to fix all old posts:
## Results
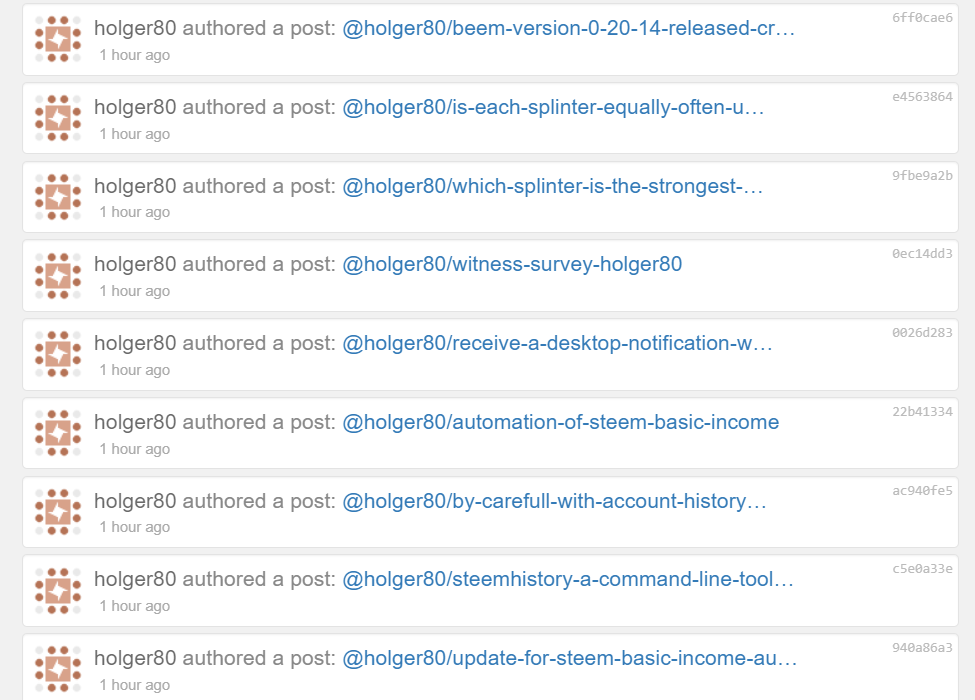
All changes have been broadcasted:
The links have been corrected, as shown here:
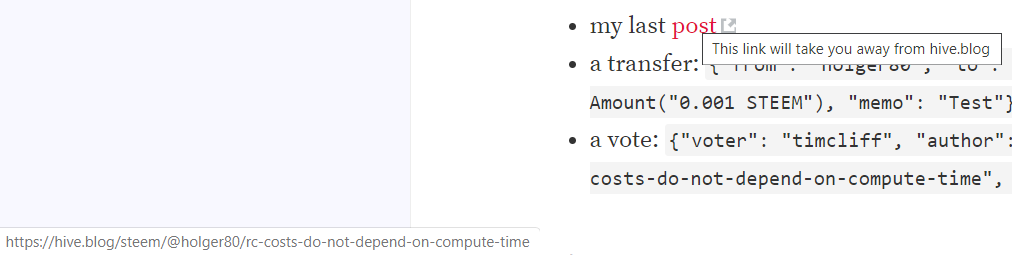
There seems to be a bug with hive.blog, that steemit.com links are shown as internal and hive.blog links are shown as external links.
The canonical url is also fixed:
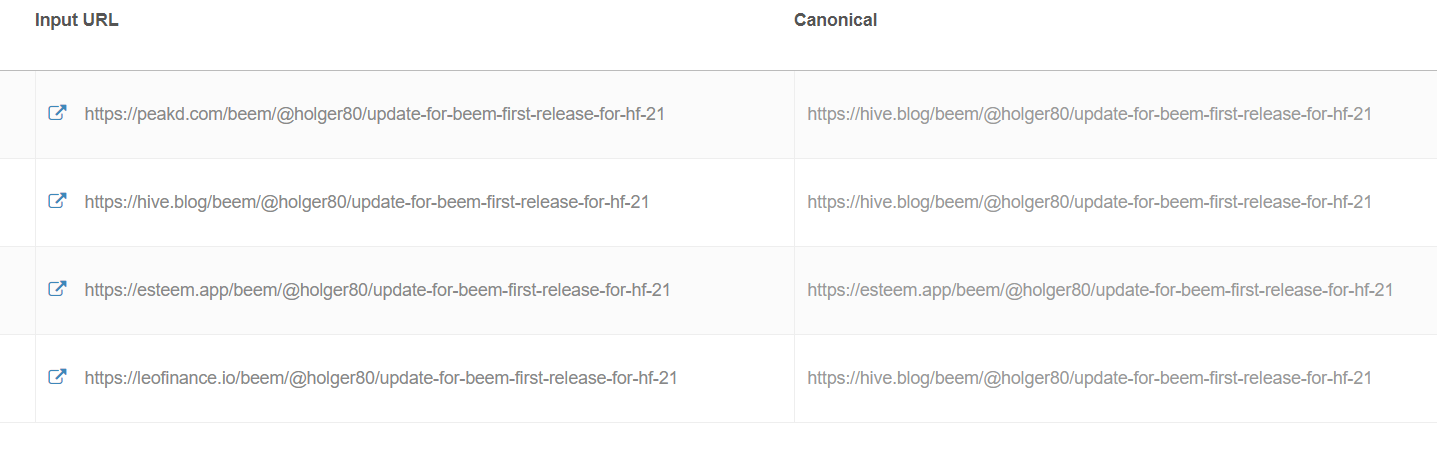
It seems that esteem.app has not changed its canonical url right now. As I know that esteem.app should read the `canonical_url` parameter (works for steempress), it may correct the canonical URLs later.
___
*If you like what I do, consider casting a vote for me as witness on [Hivesigner](https://hivesigner.com/sign/account-witness-vote?witness=holger80&approve=1) or on [PeakD](https://peakd.com/witnesses)*
Archive post